
Industry Insights
September 17, 2026
AI Data Management for Scalable Physical AI
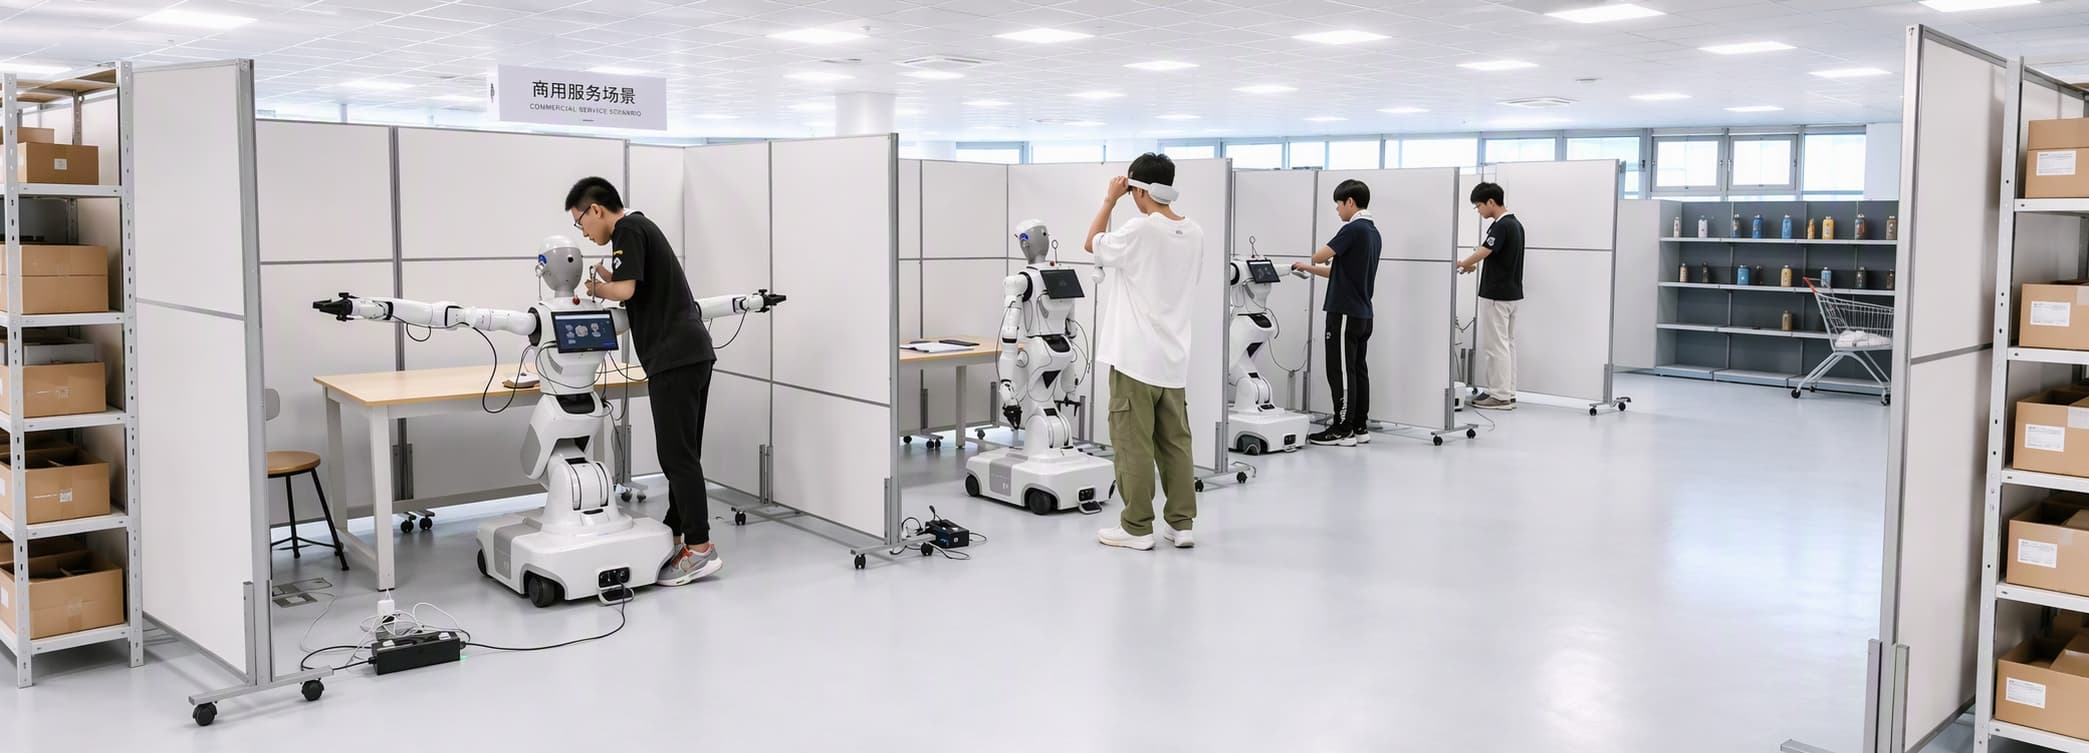
As AI systems move from digital environments into the physical world, data management is becoming an infrastructure problem rather than a simple data preparation task.
For Physical AI, model development depends on heterogeneous data collected from real-world environments: video, images, LiDAR, trajectories, sensor streams, task instructions, human demonstrations, and robot-environment interactions. These datasets are not only large in volume; they are also highly structured, temporally dependent, multimodal, and continuously evolving.
At BodenAI, we approach AI data management as a full-stack data infrastructure problem. The objective is not simply to organize datasets, but to establish a controllable pipeline connecting data collection, processing, annotation, validation, quality assurance, dataset iteration, and model development.
For Physical AI in particular, the quality of this infrastructure directly affects how efficiently models can learn from increasingly complex real-world scenarios.
AI Data Management Is Becoming a Model Development Infrastructure
Traditional data workflows are often designed around storage and retrieval. AI data management has a different requirement: data must remain usable throughout an iterative model-development lifecycle.
A production AI pipeline typically involves repeated cycles of:
Data Collection → Processing → Annotation → Quality Control → Dataset Construction → Model Training → Evaluation → Failure Analysis → Targeted Data Collection
This means data cannot be treated as a static asset.
Every new model evaluation can reveal previously unseen failure modes. Those failures create new data requirements, which then feed back into collection and annotation workflows.
For this reason, we design AI data infrastructure around continuous iteration rather than one-time dataset production.
The infrastructure needs to answer not only whether data exists, but also:
- What scenarios does the dataset represent?
- Which edge cases are missing?
- How was each data asset processed?
- Which annotation specification was applied?
- Which quality-control stages did it pass?
- Which dataset version contains the asset?
- How does a new data iteration relate to model performance?
These questions become increasingly important as AI development moves toward production scale.
Physical AI Makes AI Data Management More Complex
Physical AI introduces an additional dimension to data management: the physical state of the environment changes over time.
A robot does not simply classify an image. It observes an environment, interprets spatial relationships, predicts actions, interacts with objects, and generates new observations through those actions.
The resulting data is therefore inherently multimodal and temporal.
A single task may contain:
- RGB or multi-camera video
- Depth information
- LiDAR point clouds
- Robot state
- End-effector trajectories
- Object poses
- Action sequences
- Natural-language instructions
- Environmental context
- Human demonstrations
- Task success or failure signals
These modalities cannot always be processed independently.
Temporal synchronization, spatial relationships, object identity, action-state alignment, and task-level semantics may all affect the usefulness of the final training sample.
This is why we treat multimodal compatibility as a core requirement of AI data management rather than an optional capability.
Our Physical AI data infrastructure is designed around this requirement, connecting real-world robot training, production-grade datasets, scalable data processing, and continuous validation.
From Raw Data to Training-Ready Data
The transformation from raw data to training-ready data is not a single annotation step.
It is a sequence of controlled transformations.
Data Ingestion and Structuring
The first challenge is establishing a consistent representation across heterogeneous data sources.
For Physical AI, raw data can originate from different sensors, robots, environments, collection protocols, and task configurations.
Before annotation, we need to establish relationships between these assets.
A video sequence, trajectory and sensor stream may describe the same interaction. If these relationships are lost during ingestion, downstream annotation and model training become significantly more difficult.
Therefore, data ingestion should preserve:
- Temporal relationships
- Sensor relationships
- Session metadata
- Task identifiers
- Environment information
- Collection conditions
- Device and configuration information
This metadata layer becomes the foundation for subsequent dataset management.
Annotation as Structured Data Transformation
For complex AI systems, annotation is better understood as structured data transformation than simple labeling.
A robotic manipulation dataset, for example, may require information about:
- Object identity
- Object attributes
- Spatial relationships
- Contact states
- Human actions
- Robot actions
- Temporal events
- Task stages
- Success and failure conditions
Different model architectures may require different representations of the same underlying data.
This is where configurable annotation schemas become important.
At BodenAI, we use dynamic templates and modular workflows to support different data types and task requirements. Our platform is designed to accommodate multi-type labeling, configurable templates, and reusable workflow components rather than forcing every project into a fixed annotation structure.
Data Quality Must Be Engineered Into the Pipeline
One of the most important principles we apply to AI data management is that data quality cannot be added at the end of the pipeline.
Quality needs to be measurable throughout the entire workflow.
For large-scale Physical AI datasets, quality control may involve multiple dimensions:
Semantic Consistency
Annotations must accurately represent the intended task semantics.
For long-horizon robot tasks, this includes maintaining consistency across multiple actions and states rather than validating individual samples independently.
Temporal Consistency
Actions, observations, and state transitions need to remain logically aligned across time.
A small temporal error can propagate through a trajectory and affect the interpretation of an entire task sequence.
Spatial Consistency
For 3D and robotic applications, object positions, trajectories, and spatial relationships need to remain geometrically coherent.
Distribution Quality
Dataset quality is also a dataset-level property.
Even highly accurate annotations can produce a weak training dataset if the distribution is dominated by a narrow set of environments, object configurations, task types, or operating conditions.
We therefore consider scenario coverage, distribution, edge cases, and bias as part of quality management rather than separate analytics tasks.
Human-in-the-Loop Quality Control at Scale
Automation is essential for processing large AI datasets, but complex Physical AI data still requires expert judgment.
Our quality-control architecture combines human expertise with systematic process controls.
A typical multi-stage workflow can include:
Expert Execution → Dedicated QA → Senior Expert Sampling → Consistency and Distribution Checks → Final Acceptance
This approach allows quality controls to operate at different levels of the data hierarchy.
Individual samples can be inspected for correctness, while dataset-level analysis can identify distribution problems that may not be visible from sample-level review.
Our security and data-quality framework incorporates human-in-the-loop pipelines, multi-stage QA, consistency checks, logical validation, and distribution-level controls. For million-scale datasets, this approach is designed to maintain production-grade quality while preserving scalability.
Dataset Lineage Is Critical for AI Iteration
As model development becomes increasingly iterative, dataset lineage becomes an essential component of AI data management.
Consider a model failure discovered during evaluation.
The engineering team may need to determine:
- Which dataset contained the relevant scenario?
- Which version of the annotation specification was used?
- Which processing pipeline generated the sample?
- Which quality-control stage approved it?
- Whether similar samples exist elsewhere in the dataset?
- Whether the failure represents an isolated sample or a systematic data gap?
Without dataset lineage, these questions become difficult to answer reliably.
A production-grade data infrastructure should maintain relationships between source data, processing operations, annotations, quality checks, dataset versions, and downstream usage.
This creates a traceable data graph rather than a collection of disconnected files.
For Physical AI, this traceability is particularly valuable because model failures often need to be translated into new data collection requirements.
AI Data Management Should Close the Model-to-Data Loop
The most important shift in modern AI data management is the transition from dataset production to data feedback loops.
A mature Physical AI pipeline should operate approximately as follows:
Real-World Interaction
↓
Data Collection
↓
Data Processing & Annotation
↓
Quality Validation
↓
Training Dataset
↓
Model Training
↓
Evaluation
↓
Failure Analysis
↓
Targeted Data Collection
↓
New Dataset Version
The last stage should feed directly back into the beginning of the process.
This allows teams to focus new data collection on actual model weaknesses instead of continuously expanding datasets without a clear objective.
The result is a more efficient relationship between data volume and model performance.
Workflow Orchestration Becomes a Core Infrastructure Layer
As dataset complexity increases, manually coordinating individual data operations becomes increasingly inefficient.
Different projects may require different combinations of:
- Data collection
- Annotation
- Review
- Rework
- Quality inspection
- Sampling
- Acceptance
- Dataset release
The workflow itself therefore needs to become configurable.
At BodenAI, our platform uses agile orchestration and modular workflow architecture to support different R&D and enterprise-scale AI data requirements. Workflows can be configured around project-specific processes while reusable components make it possible to expand the system as new data types and task requirements emerge.
This is particularly important for Physical AI, where data requirements can change rapidly as model architectures, robot platforms, and task definitions evolve.
Explore our AI data platform to see how we structure data processing, quality validation, workflow orchestration, and multimodal data operations within one infrastructure.
Multimodal Data Requires Unified Data Operations
The increasing convergence of vision, language, spatial perception, and action models creates another requirement for AI data management: multimodal data must be managed as a connected system.
For example, a robot instruction may be represented as language, while execution is represented through video and trajectory data.
The relationship between these modalities is itself part of the training signal.
If the instruction, visual observation, action sequence, and outcome are stored independently, it becomes difficult to preserve the semantic relationship between them.
A unified multimodal data pipeline can instead maintain these relationships throughout processing and dataset construction.
This is particularly relevant for:
- Vision-language-action models
- Robot manipulation
- Autonomous systems
- Agent interactio
- Long-horizon task learning
- Multimodal foundation models
The infrastructure therefore needs to support multiple data types while preserving their relationships and metadata.
Security Must Be Embedded Into AI Data Management
At production scale, data security cannot exist outside the AI data pipeline.
AI datasets may contain proprietary model-development data, sensitive environmental information, human-generated content, or data collected from controlled production environments.
Security controls therefore need to exist at the infrastructure and workflow levels.
Our approach includes:
- Project and client-level data isolation
- Role-based access control
- Permission management
- Operation logging
- Audit trails
- Secure data storage
- Encrypted transmission
- Dedicated secure production environments
- Data anonymization and de-identification workflows
These controls are integrated into the broader data lifecycle rather than treated as an independent operational layer.
For teams operating large-scale or sensitive AI data pipelines, we recommend evaluating security together with data architecture, workflow design, and quality management.
Read more about our security and data quality framework.
Designing AI Data Management for Scale
Scaling AI data management is not simply a matter of increasing storage capacity or adding more annotation workers.
The architecture itself needs to scale across several dimensions simultaneously:
Data Volume
The system must process increasingly large datasets without turning data operations into a bottleneck.
Data Complexity
More modalities, longer sequences, richer metadata, and more sophisticated annotation schemas increase processing complexity.
Workflow Complexity
Different models and applications require different data pipelines, validation logic, and acceptance criteria.
Quality Requirements
As datasets become larger, maintaining consistent quality requires systematic controls rather than relying on individual inspection.
Iteration Frequency
Model development cycles are becoming shorter, which means data infrastructure must support rapid dataset updates without rebuilding the entire pipeline.
This is why we design AI data infrastructure around modularity, configurable workflows, multimodal compatibility, and continuous iteration.
Our platform is built to cover the AI data pipeline from data operations to large-scale validation, with dynamic templates, agile orchestration, and modular architecture designed for expansion.
AI Data Management Is Becoming the Foundation of Physical AI
The next stage of Physical AI will depend not only on better model architectures, but also on the infrastructure used to generate, validate, and continuously improve the data behind those models.
From our perspective, effective AI data management has four fundamental characteristics:
It is multimodal.The infrastructure must preserve relationships between vision, spatial, language, trajectory, and interaction data.
It is quality-driven.Quality needs to be engineered into the pipeline through measurable validation and human-in-the-loop processes.
It is iterative.Datasets must evolve according to model failures and changing real-world requirements.
It is infrastructure-level.Data collection, processing, annotation, quality control, orchestration, security, and dataset delivery need to operate as connected components.
For Physical AI, this changes the role of data infrastructure entirely.
The goal is no longer simply to produce a large dataset.
The goal is to build a continuous data engine capable of converting real-world interactions into high-quality training signals and feeding model performance back into the next generation of data.
That is the foundation we are building at BodenAI.
If you are developing Physical AI models, scaling multimodal datasets, or designing a production-grade AI data pipeline, contact our technical team to discuss your data infrastructure requirements.